Eleven Realtime joins our voice benchmark
We have added Eleven Realtime Mini and Max to our internal cross-customer voice benchmark. Each model completes ten scenarios three times, covering tasks such as correcting a reference, saving interview answers and handling requests it cannot fulfil.
Mini scored 70.9% and Max 87.7%, compared with OpenAI’s 79.7%. Both scored below our earlier Gemini and Dialt results. Both Eleven models also had slower median responses than Dialt Fast.
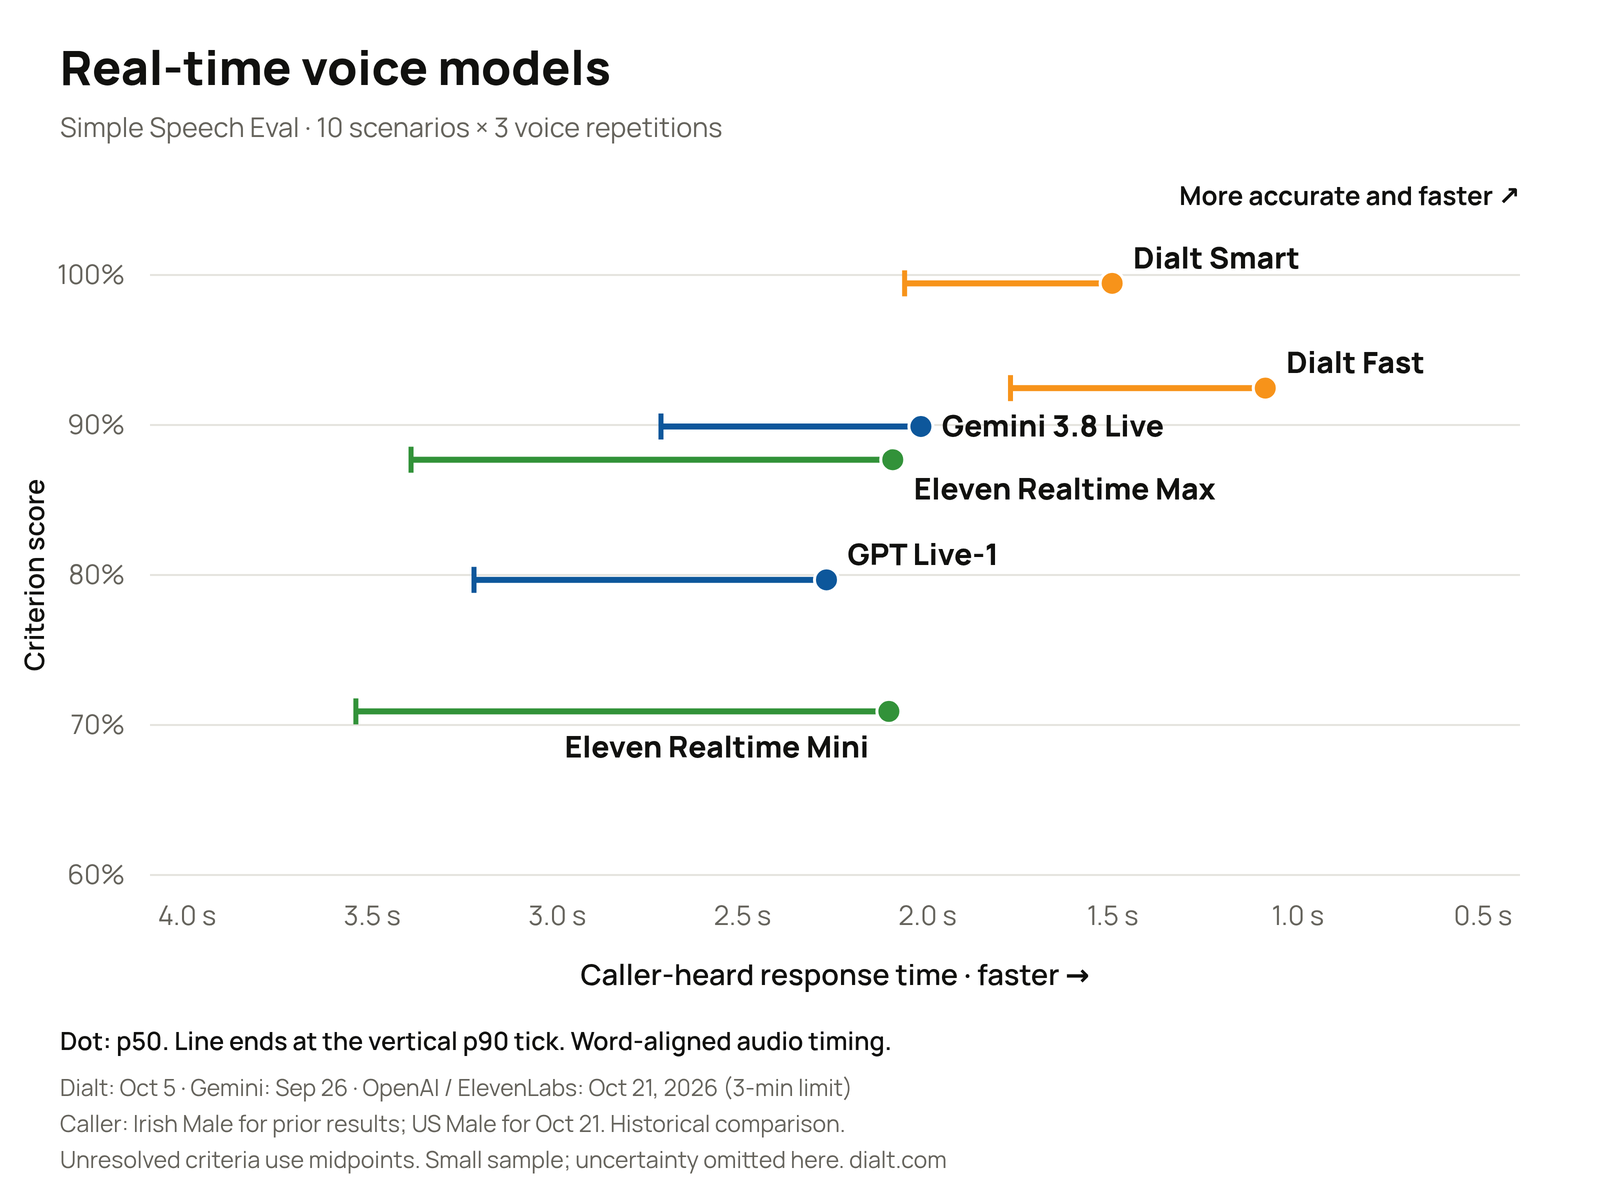
The score measures case-specific criteria, assessed by an automated judge. Unresolved criteria contribute their midpoint. Ten scenarios are a small sample, and the chart omits uncertainty intervals for readability. These results describe our tasks and configurations, not general intelligence. Response time uses word-level audio alignment, from the caller’s last word ending to the assistant’s first word beginning.
We reviewed all 90 new conversations and checked Eleven’s tool events against its own records. Mini said it had recorded interview answers without saving them in all three repetitions. Max saved every answer in two of three, but missed some writes elsewhere. OpenAI sometimes wandered into general advice or garden history instead of collecting the specified information.
Median completed-call lengths were about 103 seconds for Mini, 79 for Max and 84 for OpenAI. We fixed a harness cutoff and raised the limit from two to three minutes for these reruns and future evaluations. Neither Eleven model reached the limit; OpenAI reached it twice. A time limit alone is not a task failure. Interrupted runs were repeated; the data notes list exclusions.
Download the large-type chart · Chart data and measurement dates