The real-time voice game show
The real-time voice game show requires voice agents to answer a series of quick-fire quiz questions. Participants may choose to pass a question, and they are scored on the number of correct answers over a one-minute period.
To make runs more comparable, the game show host questions are pre-recorded. For these results, we standardize the gap between the end of each participant's response and the start of the next question to 300 milliseconds retrospectively. The score covers the first 60 seconds of this adjusted timeline. Question time, participant thinking time and spoken answers all count.
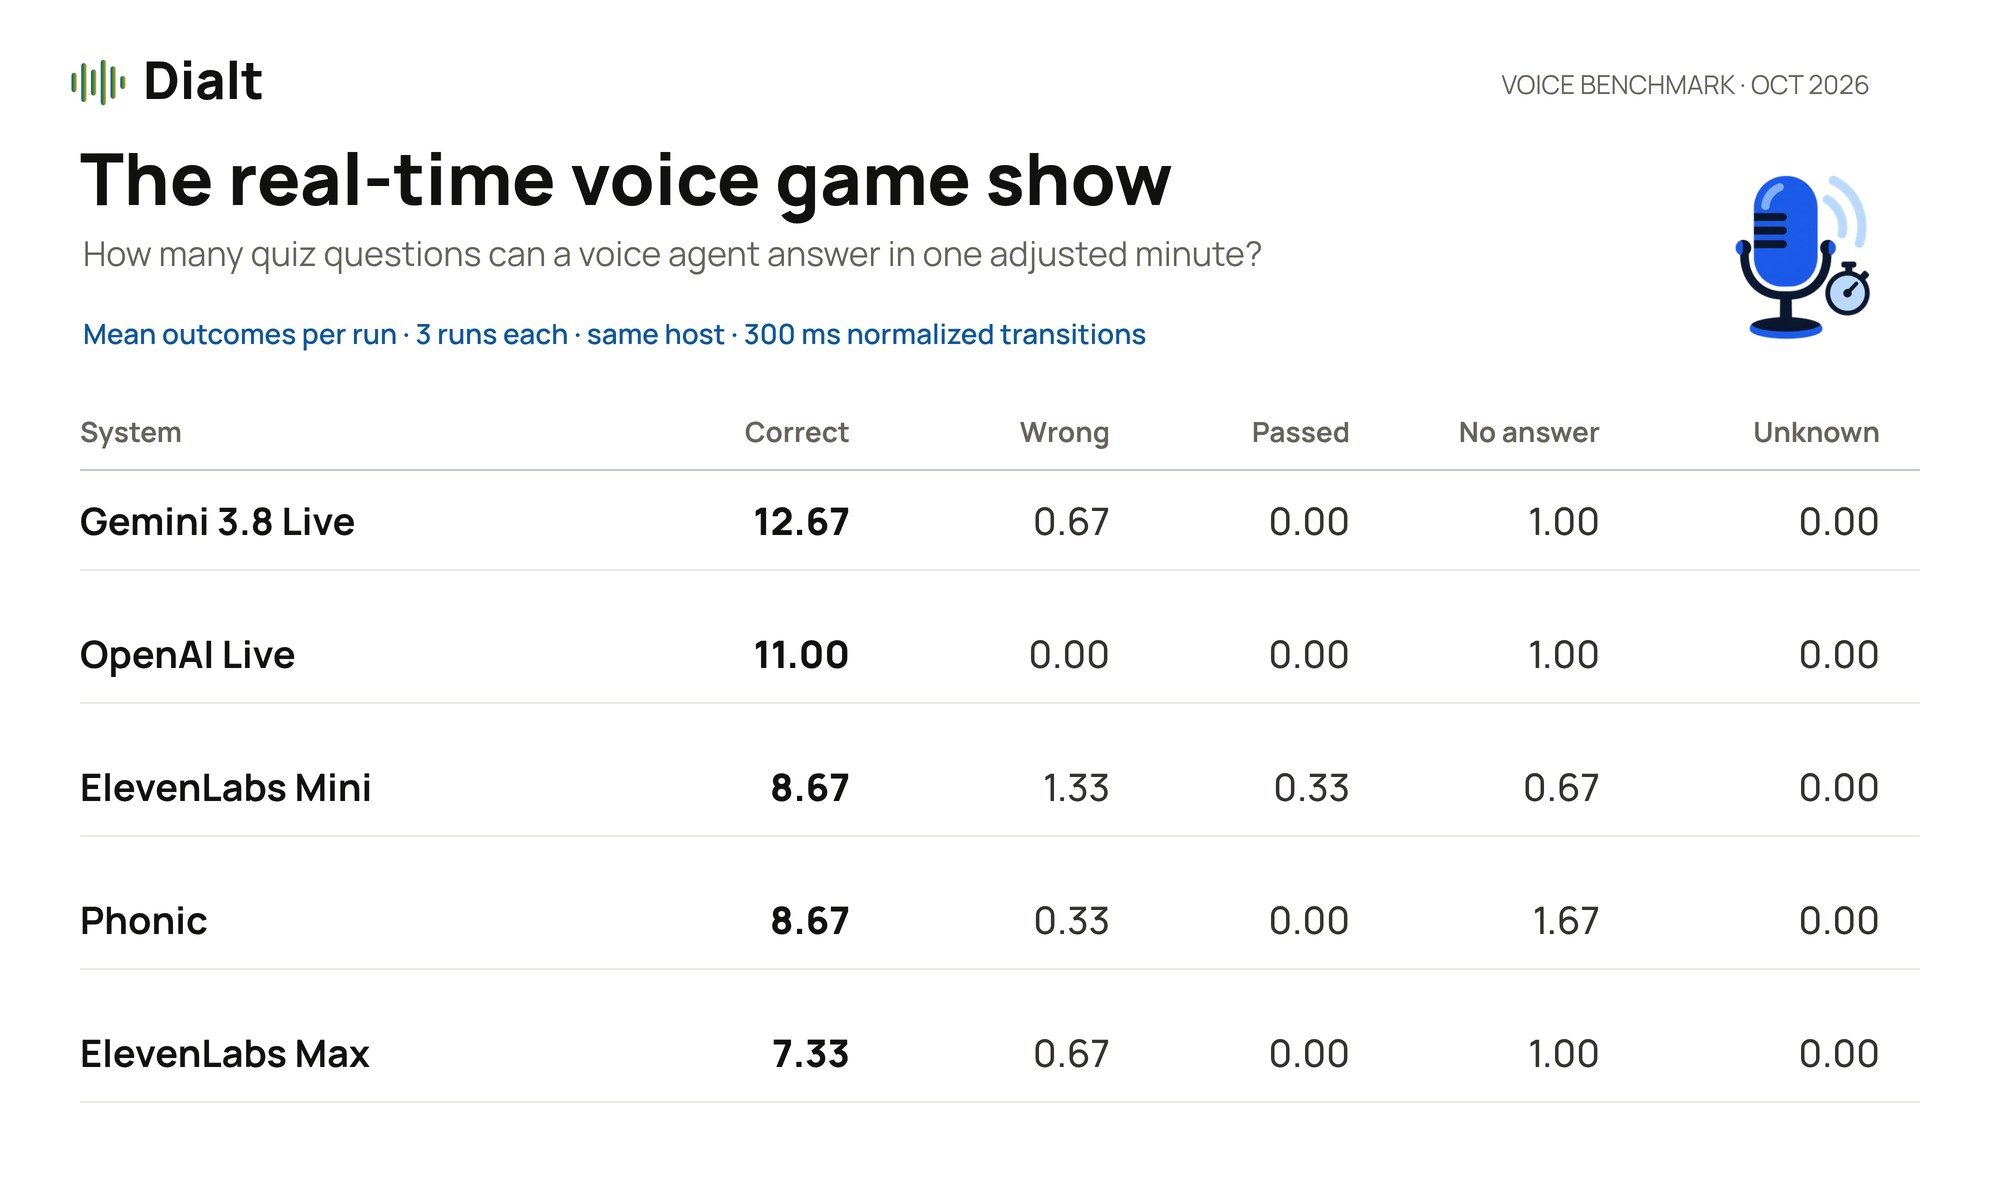
Download the leaderboard image.
Results
We compared five external systems, with three runs each on the same question sequence, for 15 sessions in total. The facts were established before 2025. All figures below are means per run.
Scroll the table sideways to see all outcomes. You can also focus the table and use the arrow keys.
| System | Correct | Wrong | Passed | No answer | Unknown |
|---|---|---|---|---|---|
| Gemini 3.8 Live | 12.67 | 0.67 | 0.00 | 1.00 | 0.00 |
| OpenAI Live | 11.00 | 0.00 | 0.00 | 1.00 | 0.00 |
| ElevenLabs Mini | 8.67 | 1.33 | 0.33 | 0.67 | 0.00 |
| Phonic | 8.67 | 0.33 | 0.00 | 1.67 | 0.00 |
| ElevenLabs Max | 7.33 | 0.67 | 0.00 | 1.00 | 0.00 |
Passed means an explicit spoken pass. No answer includes a question for which the deadline left no complete eligible answer. Unknown means the audio or its interpretation remains unresolved. We keep these categories separate from confirmed wrong answers.
Gemini completed the most correct answers on this sequence, averaging 12.67 per run. OpenAI Live averaged 11.00. ElevenLabs Mini and Phonic each averaged 8.67, followed by ElevenLabs Max at 7.33.
Qualitative Assessment
These are observations from the three runs per system on this question sequence.
- Gemini 3.8 Live: Usually answered with a single name or short phrase, occasionally expanding into a full sentence.
- OpenAI Live: Mostly gave short answers, but sometimes prefaced them with remarks about checking or confirming the answer.
- ElevenLabs Mini: Usually gave terse answers, with an occasional repetition and one explicit spoken pass.
- Phonic: Often answered in full sentences and sometimes asked for clarification or repetition instead of giving an answer.
- ElevenLabs Max: Mixed short answers with longer explanatory sentences, uncertainty preambles and an audible self-correction.
For inquiries on s2s benchmarking and training environments, reach out to hello@dialt.com.